Health check
ML servers often go unmonitored or rely on generic health checks that don’t reflect model readiness or infrastructure status. This can lead to undetected failures, delayed responses, or unstable production deployments; especially in environments with autoscaling or load balancing. LitServe provides built-in and customizable health check endpoints that let developers monitor server status, define what “healthy” means, and expose it at any path.
Overview
What is a health check?
A health check is a lightweight endpoint that lets external systems (like load balancers or monitoring tools) verify whether your ML server is operational. It helps with uptime monitoring, auto-scaling, and graceful recovery during failures.
LitServe health check
LitServe provides a built-in health check endpoint at /health by default. This is an endpoint that returns a 200 OK response if the server is alive.
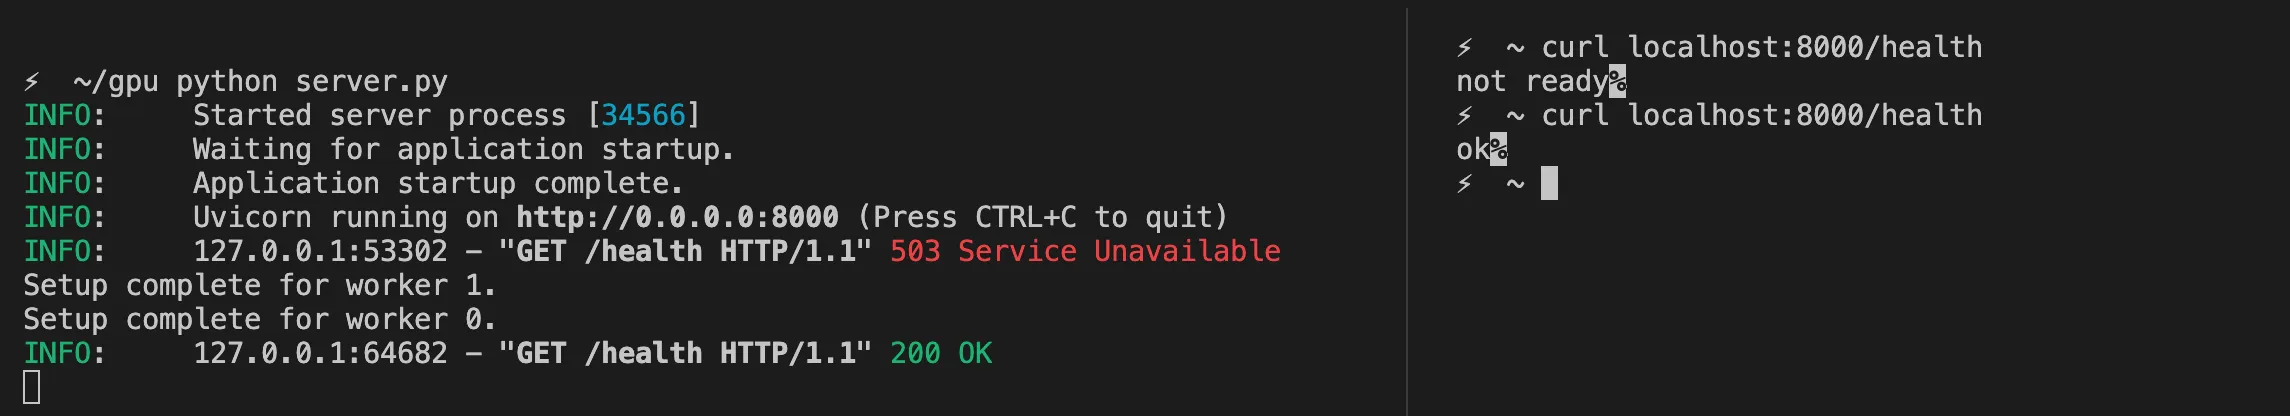
In case of multiple inference workers or multiple LitAPIs, LitServe ensures the server is ready, and it returns "ok" when all inference workers have set up, meaning they've loaded the models and are ready to handle requests.
Customization options
We can:
- Change the default health check path using
healthcheck_path - Override the logic of the health check by defining a custom health method in our API class
Health check LitServe API
By default, LitServe includes the /health endpoint at port 8000. Here's the minimal setup:
import litserve as ls

class MyAPI(ls.LitAPI):
    def setup(self, device):
        self.model = lambda x: x

    def predict(self, request):
        return self.model(request)

if __name__=="__main__":
    api = MyAPI()
    server = ls.LitServer(api)
    server.run(port=8000)  # /health available at http://localhost:8000/health
Query the server using:
curl http://localhost:8000/healthThis will return:
{
  "status": "ok"
}
Custom health check path
To serve the health check at a different path, configure healthcheck_path:
server = ls.LitServer(api, healthcheck_path="/status")
server.run(port=8000)
Now, health is served at: http://localhost:8000/status
Custom health logic
We can override the health() method in our API to control what "healthy" means:
from fastapi import HTTPException
import litserve as ls


class ExampleAPI(ls.LitAPI):
    def setup(self, device):
        self.model = lambda x: x**2

    def predict(self, request):
        return "Hello, world!"

    def health(self):
        raise HTTPException(status_code=400, detail="Health check failed")


if __name__ == "__main__":
    api = ExampleAPI()
    server = ls.LitServer(api)
    server.run(port=8000)
This will make the /health endpoint return a 400 error, useful when doing internal readiness checks or verifying model availability.
Health check failures in production
Common Issues
- Model not loaded yet
- GPU memory full or unavailable
- External service (e.g. embedding DB) unreachable
Solution approach
Define meaningful logic in the health() method to detect these and return HTTPException if the server isn't ready. Example:
from fastapi import HTTPException
import torch
import litserve as ls

class GPUCheckAPI(ls.test_examples.SimpleLitAPI):
    def health(self):
        if not torch.cuda.is_available():
            raise HTTPException(status_code=503, detail="CUDA not available")
        return True
Conclusion
Customizable health checks in LitServe help us align with production reliability standards. Whether we need basic pings or deep readiness checks, LitServe gives us the flexibility to stay observant and resilient.
Was this page helpful?
Thanks for the feedback.