Foundational AI Infrastructure for Demanding Workloads
NVIDIA GPUs housed in Tier 3+ data centers for unparalleled performance, reliability, and security.
The architecture high-performing teams trust
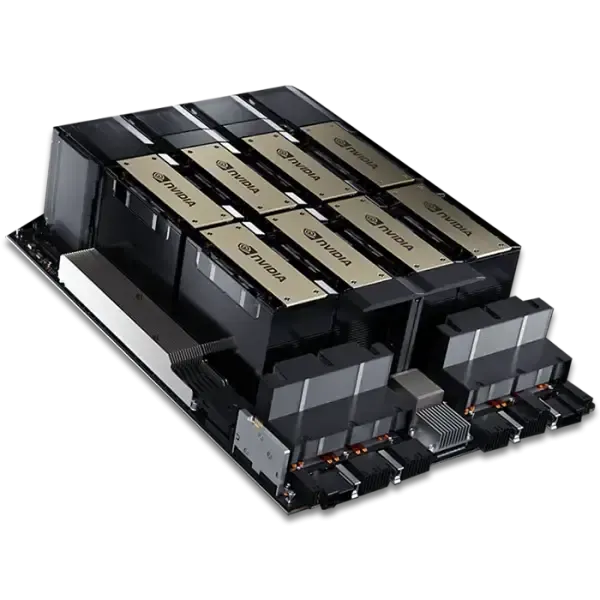
Hopper
HGX H100
Performance and scale
Train and fine-tune models with high throughput and fast interconnect.
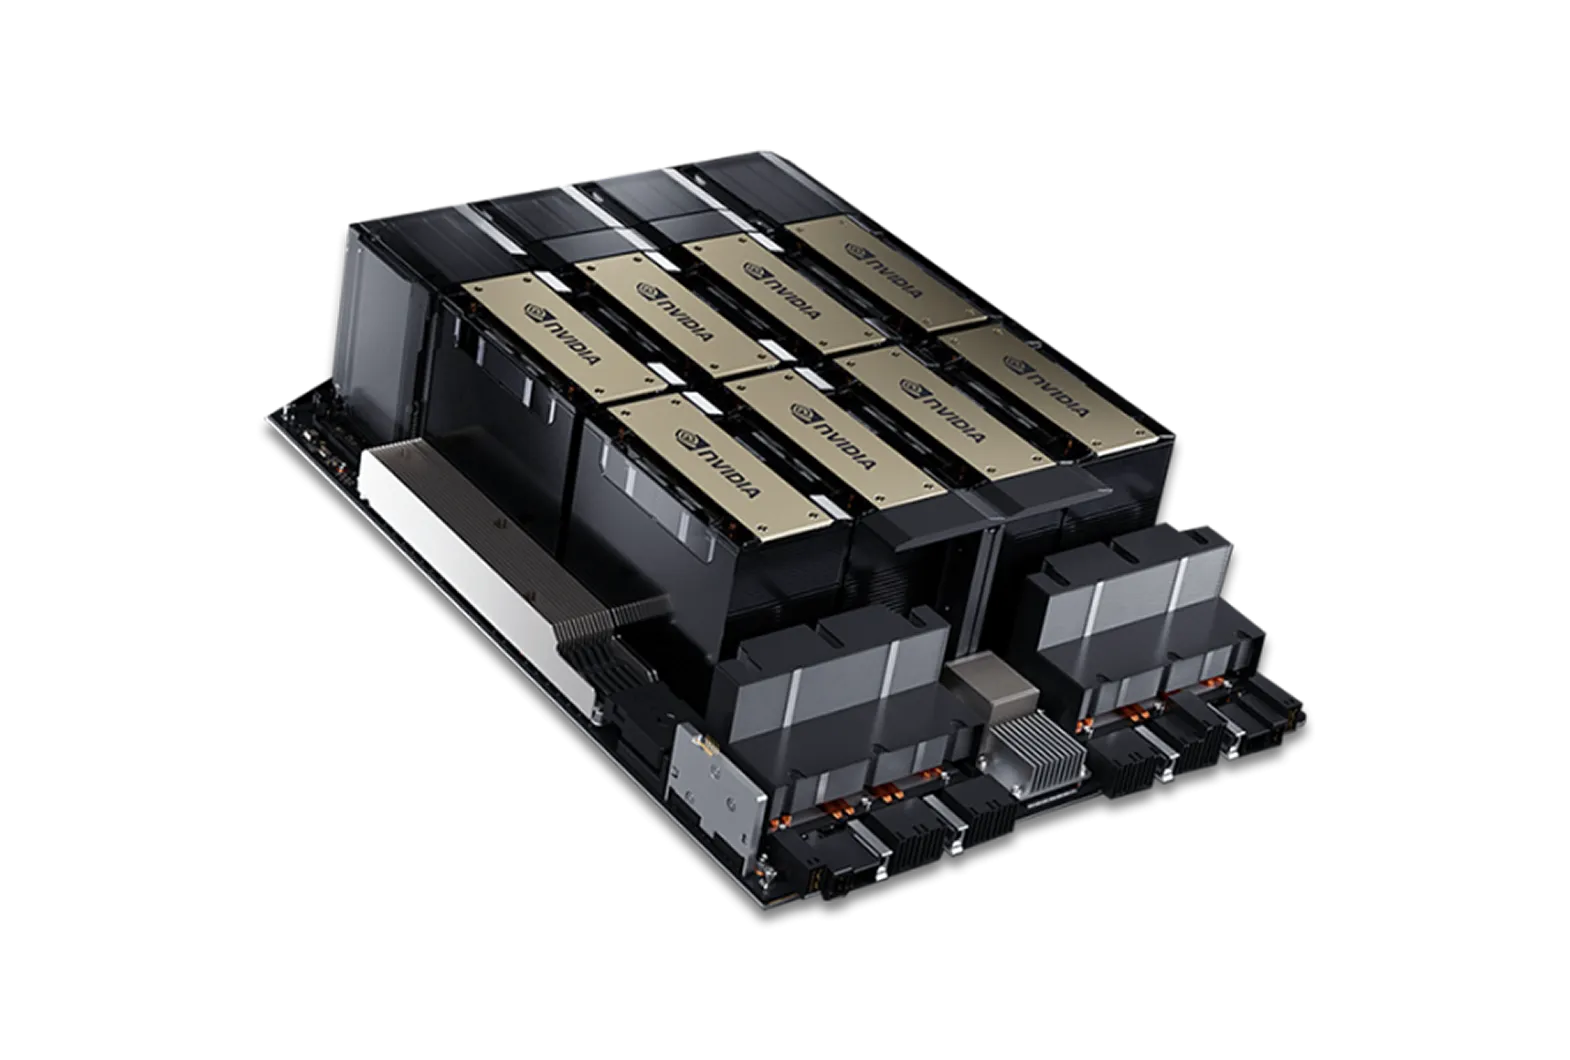
Hopper
HGX H200
Large-model memory
141GB of HBM3e memory and 4.8 TB/s of bandwidth for memory-heavy training and inference. Up to 1.9× faster inference than H100.
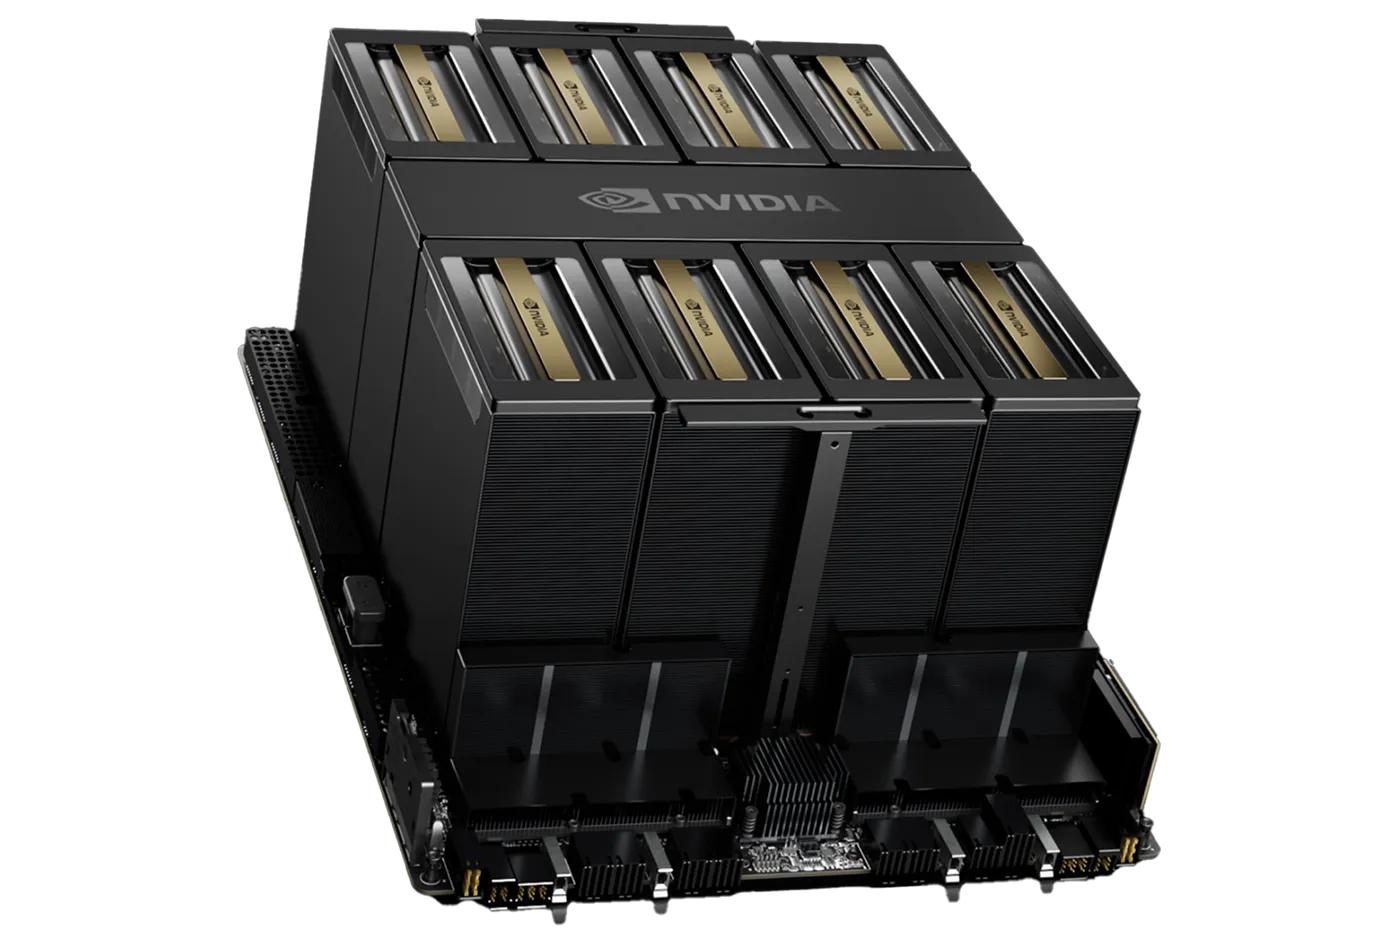
Blackwell
HGX B200
Faster training at scale
A second-generation Transformer Engine with FP8 and new precisions for efficient multi-node scaling. Up to 3× faster training than H100.
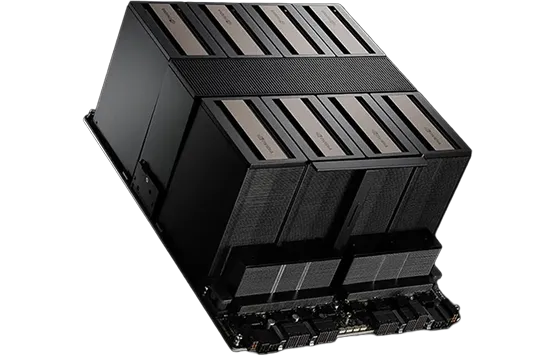
Blackwell Ultra
HGX B300
Next-gen training and inference
NVIDIA Blackwell Ultra with high-speed NVLink delivering 1.5× more NVFP4 dense compute and 2× attention performance versus HGX B200.
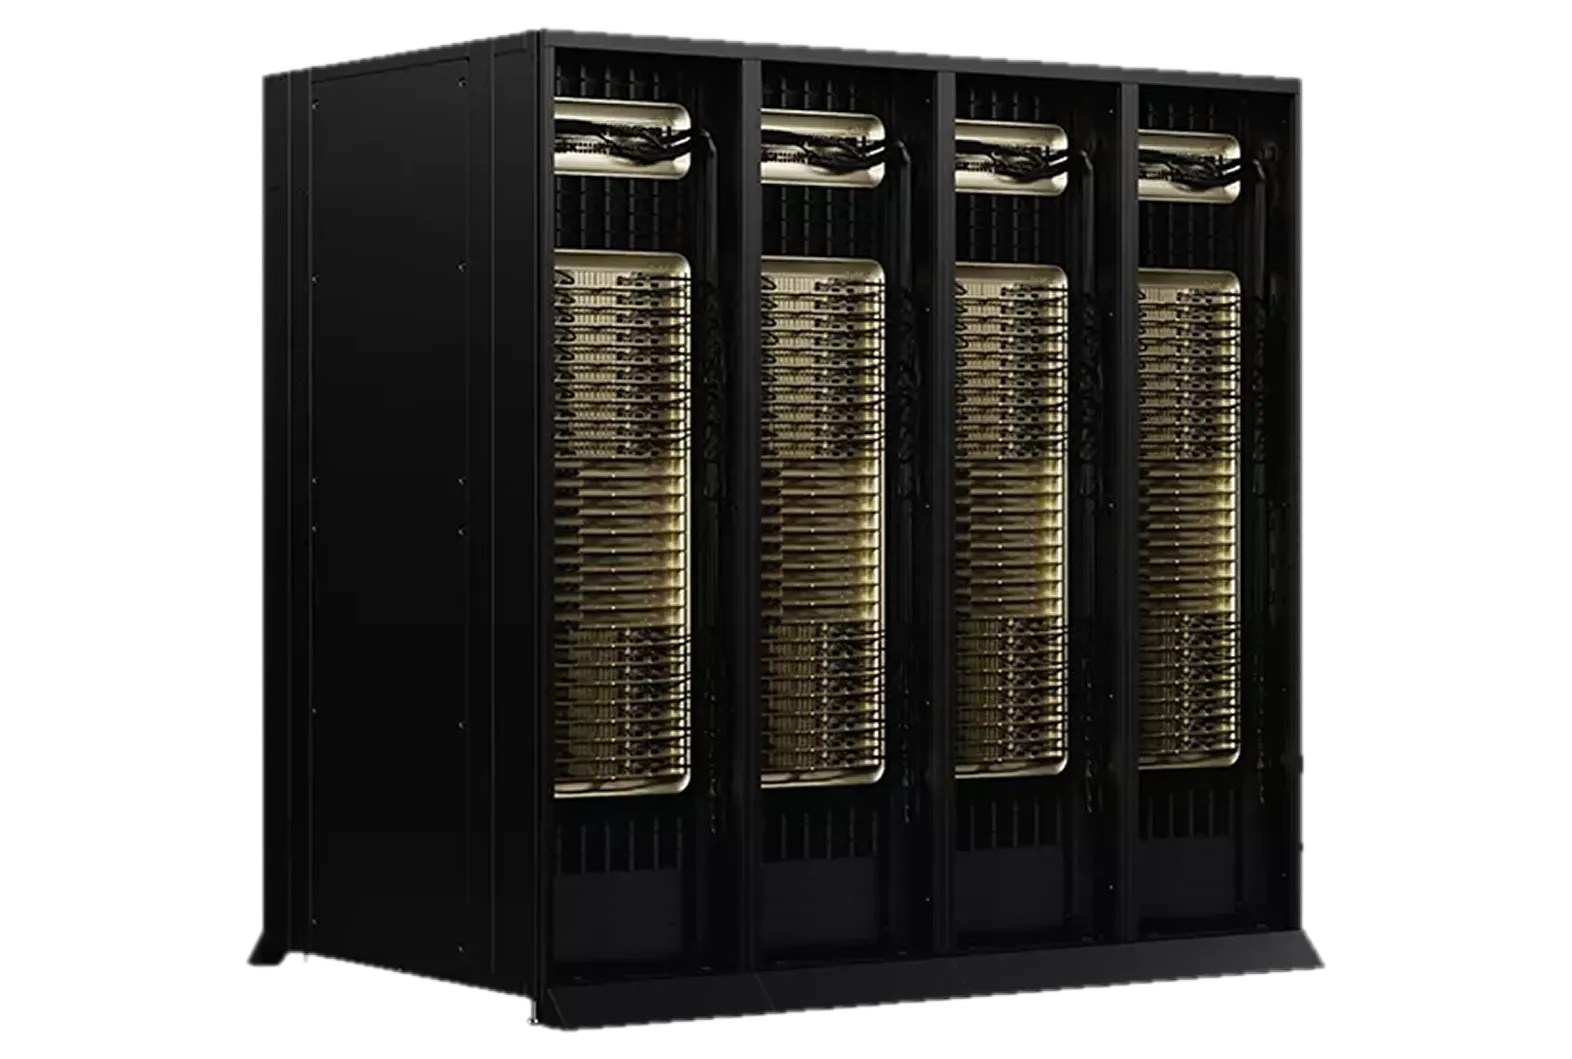
Grace Blackwell Ultra
GB300 NVL72
Reasoning at rack scale
Blackwell Ultra GPUs with NVIDIA Quantum-X800 InfiniBand or Spectrum-X Ethernet and ConnectX-8 SuperNICs offer up to 50× higher AI factory output than Hopper.
Capacity and tooling
built for AI teams
Choose how you access compute, then add the orchestration, storage,
and observability your workloads need.
On-demand and reserved capacity
Choose reserved clusters or on-demand GPUs to fit every AI team, from startups to large-scale labs. Pay only for what you use, or reserve capacity and scale as you grow.
Managed Kubernetes
Secure clusters built on upstream Kubernetes, ready in minutes, with simplified multi-node orchestration for training, fine-tuning, and inference. Works with Kubernetes-native tools, GitOps, and Terraform.
AI-optimized storage
High-performance compute connected to a unified, VAST-powered storage layer built for AI. From checkpointing trillion-parameter models to sharing datasets across thousands of nodes, your data keeps pace with your workloads.
Real-time observability
Monitor the metrics that matter across your models, GPU usage, and inference pipelines. Spot bottlenecks before they impact workloads and keep AI costs under control.
Our customers
Voltage Park has consistently provided us with some of the most affordable and reliable access to H100 multi-node machines.

Voltage Park’s owned hardware and technology meets our critical needs.

I’m very, very happy with Voltage Park. I think it’s been very critical to our success over the past couple of months.

I didn’t want to tell people what cloud provider we’re using, because the pricing is too good.
FAQs
Frequently asked questions comparing the HGX B200 and HGX B300
What’s the difference between the NVIDIA HGX B200 and HGX B300 in terms of performance and specifications?
NVIDIA HGX B200 integrates eight Blackwell GPUs, while HGX B300 integrates eight Blackwell Ultra GPUs. HGX B200 has up to 180GB of HBM3e memory per GPU and HGX B300 is equipped with 270GB per GPU—a 50% increase. Both offer 7.7 TB/s of memory bandwidth per GPU and fifth-generation NVLink providing 1.8 TB/s of GPU-to-GPU bandwidth.
Which workloads are best suited for the HGX B200?
HGX B200 accelerates AI training, large-scale inference, data analytics, and high-performance computing. Its second-generation Transformer Engine supports large language models and mixture-of-experts models, while its eight-GPU architecture supports distributed workloads.
Which workloads are best suited for the HGX B300?
HGX B300 is designed for AI reasoning, agentic systems, large-model training, and real-time video generation. Its larger memory capacity supports larger models and batches, while improved attention performance benefits demanding reasoning and long-context inference workloads.
What is the difference in pricing and availability for the HGX B200 and HGX B300?
Both the HGX B200 and HGX B300 are currently available with a long-term contract at Voltage Park. Contact us for details.
Get the right GPU
for your workload
Dedicated performance, enterprise-grade reliability, reserved or on-demand.