Introducing NVIDIA Nemotron 3 Super
Developers are building multi-agent systems with workflows where models plan, call tools, analyze data, conduct research, and iterate across multiple steps to complete real tasks.
But with multiple agents in the mix, everything gets harder.
The biggest issues we hear from teams building agent systems today are surprisingly consistent. Workflows run for hours instead of seconds, context grows uncontrollably across steps, costs explode when every task uses frontier models, model providers change behavior unexpectedly, and security teams push back on sending sensitive data to external APIs.
This is the reality of building production AI systems today.
And it's exactly the type of workload NVIDIA Nemotron 3 Super was designed for.
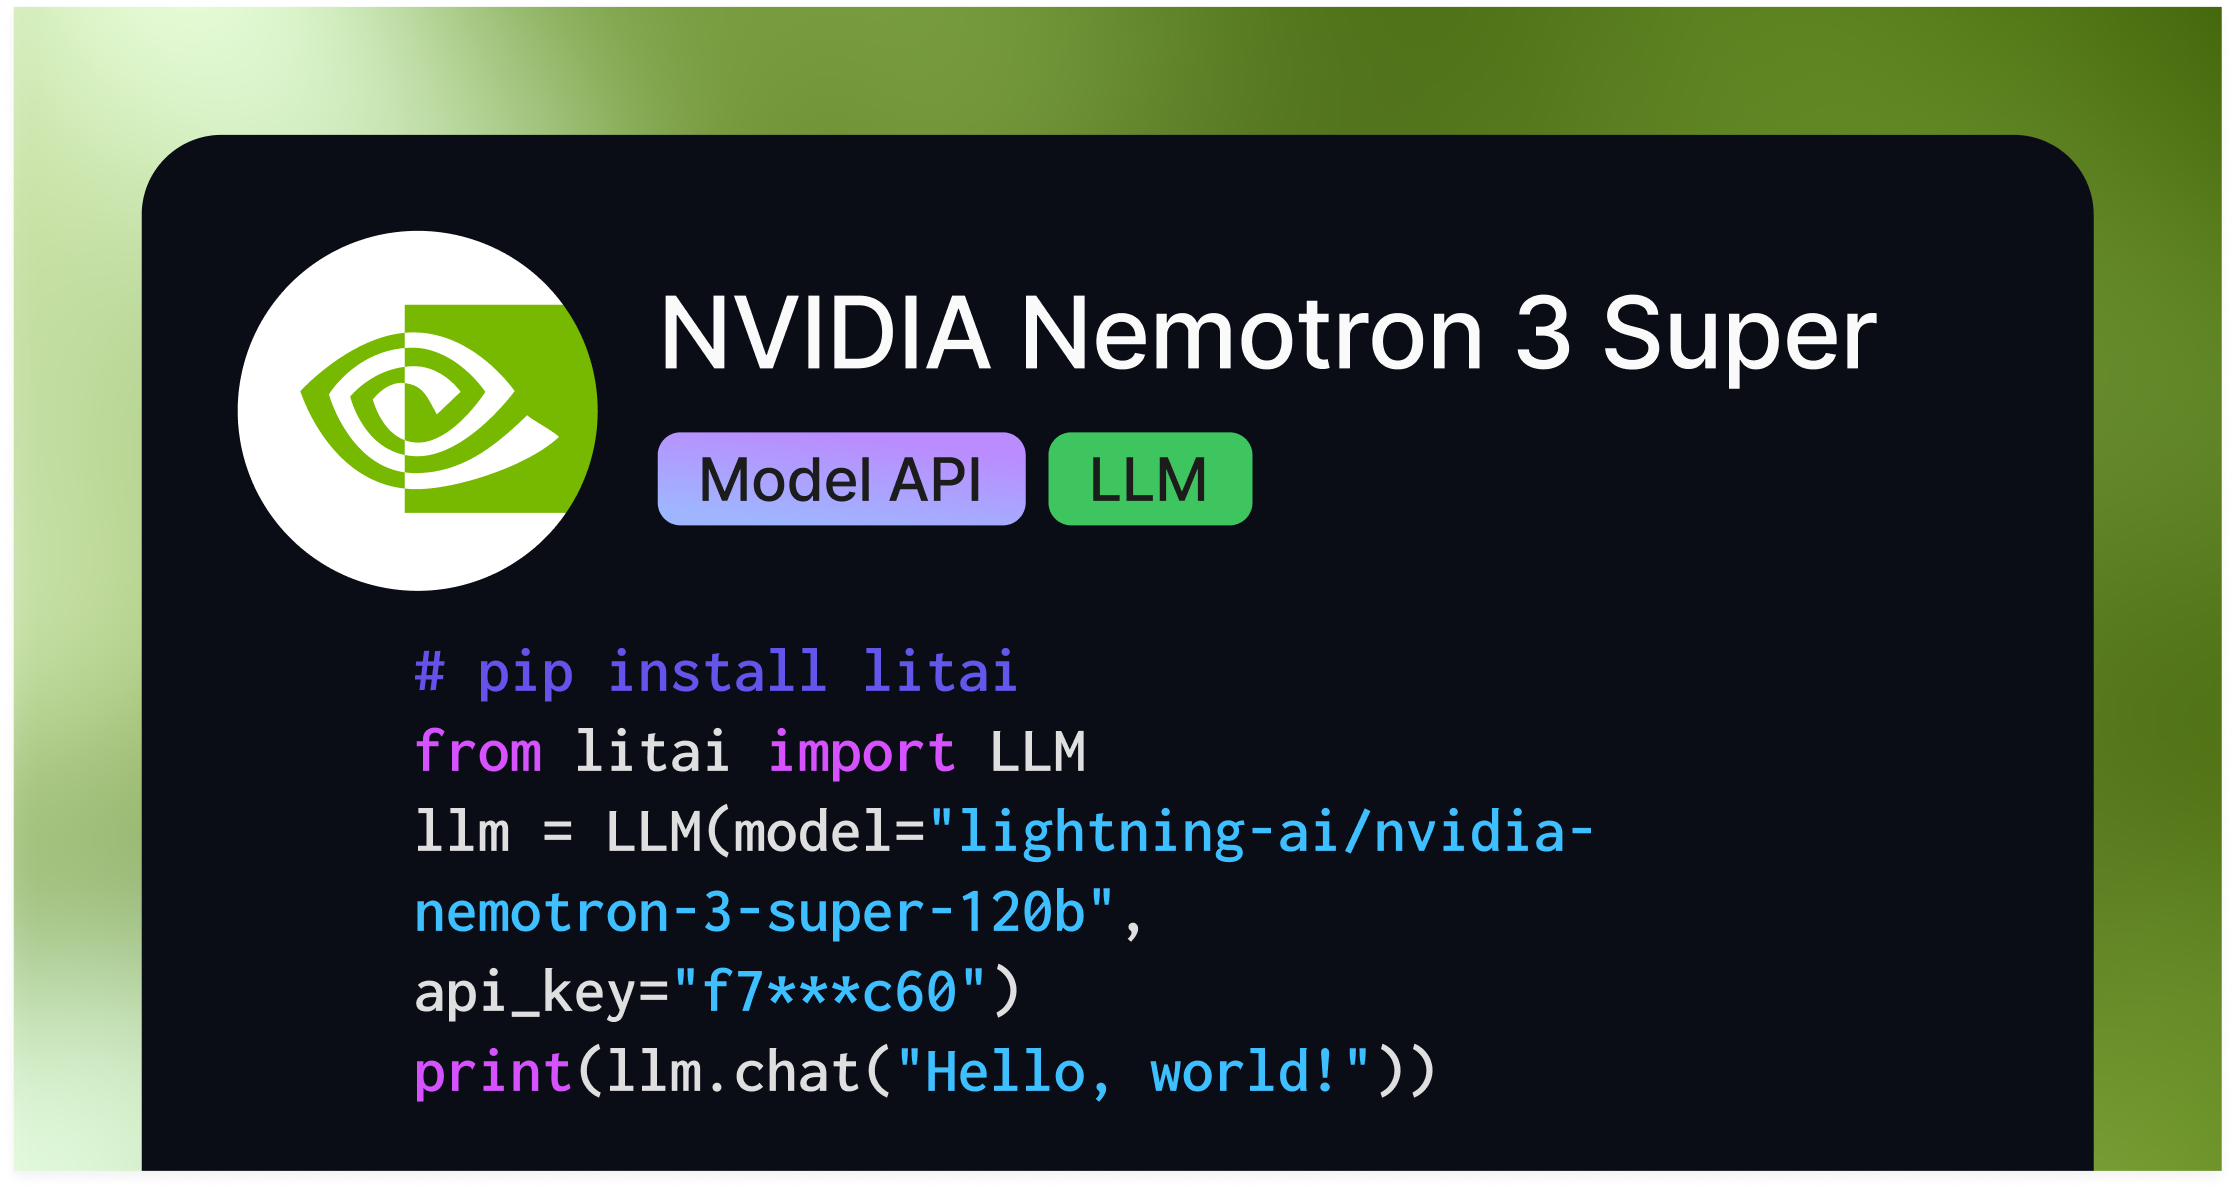
Today we’re excited to support Nemotron 3 Super on Lightning, giving developers a powerful open model for running efficient multi-step agent workflows while maintaining full control over infrastructure.
The new problem: agents multiply everything
Traditional AI apps follow a simple pattern.
response = llm.generate(user_prompt)Agent systems are fundamentally different.
A single user request can generate dozens or even hundreds of model calls as the system plans the task, selects tools, retrieves information, analyzes intermediate results, executes actions, validates outputs, and produces a final response.
A simplified agent loop often looks something like this:
def do_task(task_state):
    if task_state.goal_complete:
        return task_state.result

    plan = planner_model(task_state)

    # If the planner decides a subtask is required
    if plan.type == "subtask":
        sub_result = do_task(plan.subtask_state)
        task_state.update(sub_result)

    else:
        tool_call = tool_router(plan)
        result = execute_tool(tool_call)
        task_state.update(result)

    # Continue working on the task
    return do_task(task_state)
Each step introduces additional reasoning, intermediate context, and system complexity.
In practice this creates two major challenges.
Context explosion
Agent workflows repeatedly pass around conversation history, tool outputs, reasoning traces, and intermediate results. Over long tasks, this growing context dramatically increases token usage and often leads to goal drift, where agents slowly lose alignment with the original objective.
In real systems, agent workflows can generate 10 - 15x more tokens than standard chat interactions.
The thinking tax
Not every step in an agent pipeline needs a frontier model.
Yet many systems rely on them for everything, such as deciding which tool to call, generating search queries, reading files, summarizing intermediate results, and producing the final answer.
Using large models for all these micro-tasks makes agents slow, expensive, and difficult to scale.
Developers increasingly want to route workloads across different models, using smaller models for routing and tool calls, mid-sized models for structured reasoning, and frontier models only for the final response.
To make this architecture work, teams need powerful open models they can run and fine-tune themselves.
Enter NVIDIA Nemotron 3 Super
NVIDIA Nemotron 3 Super is a 120B-parameter hybrid Mixture-of-Experts model designed specifically for complex reasoning tasks inside agent systems.
The model introduces several architectural innovations:
Hybrid Mamba + Transformer architecture
Nemotron 3 Super combines:
- Mamba layers for efficient long-context processing
- Transformer layers for deep reasoning
This allows agents to process massive histories without the typical compute overhead.
Mixture-of-experts efficiency
Although the model has 120B parameters, only 12B are active per token during inference.
This dramatically reduces compute requirements while preserving strong reasoning capability.
Latent MoE
A new routing technique activates multiple specialized experts internally while maintaining the cost of a single model pass.
The result is higher reasoning accuracy without increasing inference cost.
Multi-token prediction
The model predicts multiple tokens simultaneously, accelerating generation and improving throughput.
Built for long agent workflows
One of the core goals of NVIDIA Nemotron 3 Super is supporting long-running agent tasks.
The model supports a one-million-token context window, allowing systems to retain the entire state of a workflow in memory.
That means agents can load an entire codebase along with tool outputs and debugging history, or analyze thousands of pages of financial documents while retaining intermediate conclusions and reasoning steps across the workflow.
Instead of repeatedly truncating context or recomputing reasoning across long conversations, agent systems can maintain their full state inside the model’s context.
For complex multi-step workflows, this dramatically simplifies system design.
Why open models matter for agent systems
Another challenge many teams face when building AI products is platform risk.
When your entire product depends on a single external API, pricing can change, model behavior can shift unexpectedly, performance can vary between versions, and security teams may require stronger guarantees about where sensitive data is processed.
For this reason, many organizations are moving toward hybrid architectures where open models handle internal workflows, document analysis, routing, and tool calling, while frontier APIs remain available for the most complex reasoning tasks.
This approach reduces cost, stabilizes system behavior, isolates sensitive data, and avoids vendor lock-in.
Nemotron 3 Super is released with open weights and training methodology, allowing teams to deploy it on their own infrastructure, fine-tune it for specific workflows, and adapt it to domain-specific tasks such as tool calling or structured analysis.
Running NVIDIA Nemotron 3 Super on Lightning
Building agent systems requires more than powerful models. Developers also need infrastructure for experimentation, training, deployment, and orchestration.
Lightning provides a unified platform for building and operating AI systems end-to-end.
Developers can experiment with NVIDIA Nemotron 3 Super across different GPU configurations, fine-tune models for specific tasks such as tool routing or document processing, and deploy scalable inference endpoints for production workloads.
Lightning also makes it easier to build multi-model agent pipelines, where different models handle different parts of a workflow.
Using Lightning’s Model APIs, developers can build a system that might use a smaller open model for tool routing and structured tasks, NVIDIA Nemotron 3 Super for deeper reasoning across large contexts, and a frontier model API only for the final response.
Each component runs on the infrastructure best suited to its workload, allowing teams to balance cost, performance, and reliability.
The Next phase of AI Systems
Agent systems introduce real challenges for developers. Massive context growth, long reasoning chains, multi-model orchestration, and the need for production stability are table stakes.
Models like NVIDIA Nemotron 3 Super are designed for this new paradigm, enabling efficient reasoning across long contexts while maintaining strong performance.
Combined with platforms like Lightning, developers can experiment with these models, fine-tune them for specialized tasks, and deploy scalable agent systems.
The future of AI isn't just smarter models.
It's reliable systems built around them.
Try Nemotron 3 Super on Lightning
Run large-context reasoning workloads, experiment with multi-agent pipelines, and deploy scalable inference endpoints, all within a unified developer platform.
Try Nemotron 3 Super on Lightning and start building reliable agent systems today.
Read more blogs and case studies
• Vibe Coding My Way to a Boltz-2 Structure Prediction App
• 5 Things to Do With MicroGPT to Get the Most Value Out of It
• View all