Starting today, applied AI teams can experiment and train on the Lightning Cloud: our vertically-integrated AI cloud we own and operate with guaranteed on-demand and spot H100 availability.
The problem with a split stack
The Lightning Cloud’s owned H100s are now the foundation for the Lightning Studios Platform.
We built it this way because we believe owning the entire stack from soil to software, is the only way to give enterprise teams the infra they can rely on in the next wave of AI evolution. When Lightning and Voltage Park merged, we did so on this very thesis. The Lightning Cloud gives enterprises and teams the reliability they need around workload placement, performance, provisioning, and price in ways that rented capacity cannot.
Most AI infrastructure platforms don’t share that vision. They lease capacity from another provider, add a software layer, and hand customers a virtual machine with limited visibility into the hardware and network underneath.
That model splits the stack:
- One company controls the physical infrastructure.
- Another operates the software above it.
If provisioning fails, topology is poorly matched, a multi-node job lands on the wrong network fabric, or network contention slows down workloads, the platform serving the customer rarely has the controls to fix it.
On the Lightning Cloud, one team owns and operates the full stack: the GPUs, the datacenter fabric, the virtualization layer, the scheduler, and the development environment. The result is a cloud built as one system, not software bolted onto rented hardware.
This moment matters for owned intelligence
Open source models are closing the capability gap faster than most enterprises expected. As the intelligence layer moves away from general purpose frontier models, the moat moves somewhere harder to copy: models specialized with proprietary data.
That data is the one asset neolabs cannot replicate, no matter how much capital they raise. But a moat only matters if you can execute against it. The Lightning Cloud lets teams own the training and experimentation cloud their data runs through with the controls sophisticated IT teams demand.
Before the Lightning Cloud guaranteed instant on-demand availability, enterprises had two paths to get compute:
Long-term reservations: Access to capacity and a competitive hourly rate, in exchange for large upfront payments, cluster utilization that seldom surpasses 66%, procurement cycles that stretch for quarters, and none of the enterprise security and controls modern teams require.
On-demand hyperscaler commitments: Enterprise-grade security and tooling, at a steep per-hour cost, on infrastructure that was never purpose-built for AI. Researchers adapt their workflow to the tools instead of the other way around resulting in dozens of experiments each month, instead of thousands.
Both divert resources away from what really differentiates businesses. The Lighting Cloud offers a third path: guaranteed H100 capacity, owned end-to-end by the platform they’re building on. Enterprise-grade reliability and researcher-built tooling is in one system so teams can truly accelerate their AI development and training to create a step-change impact on their business.
The Lightning Cloud features
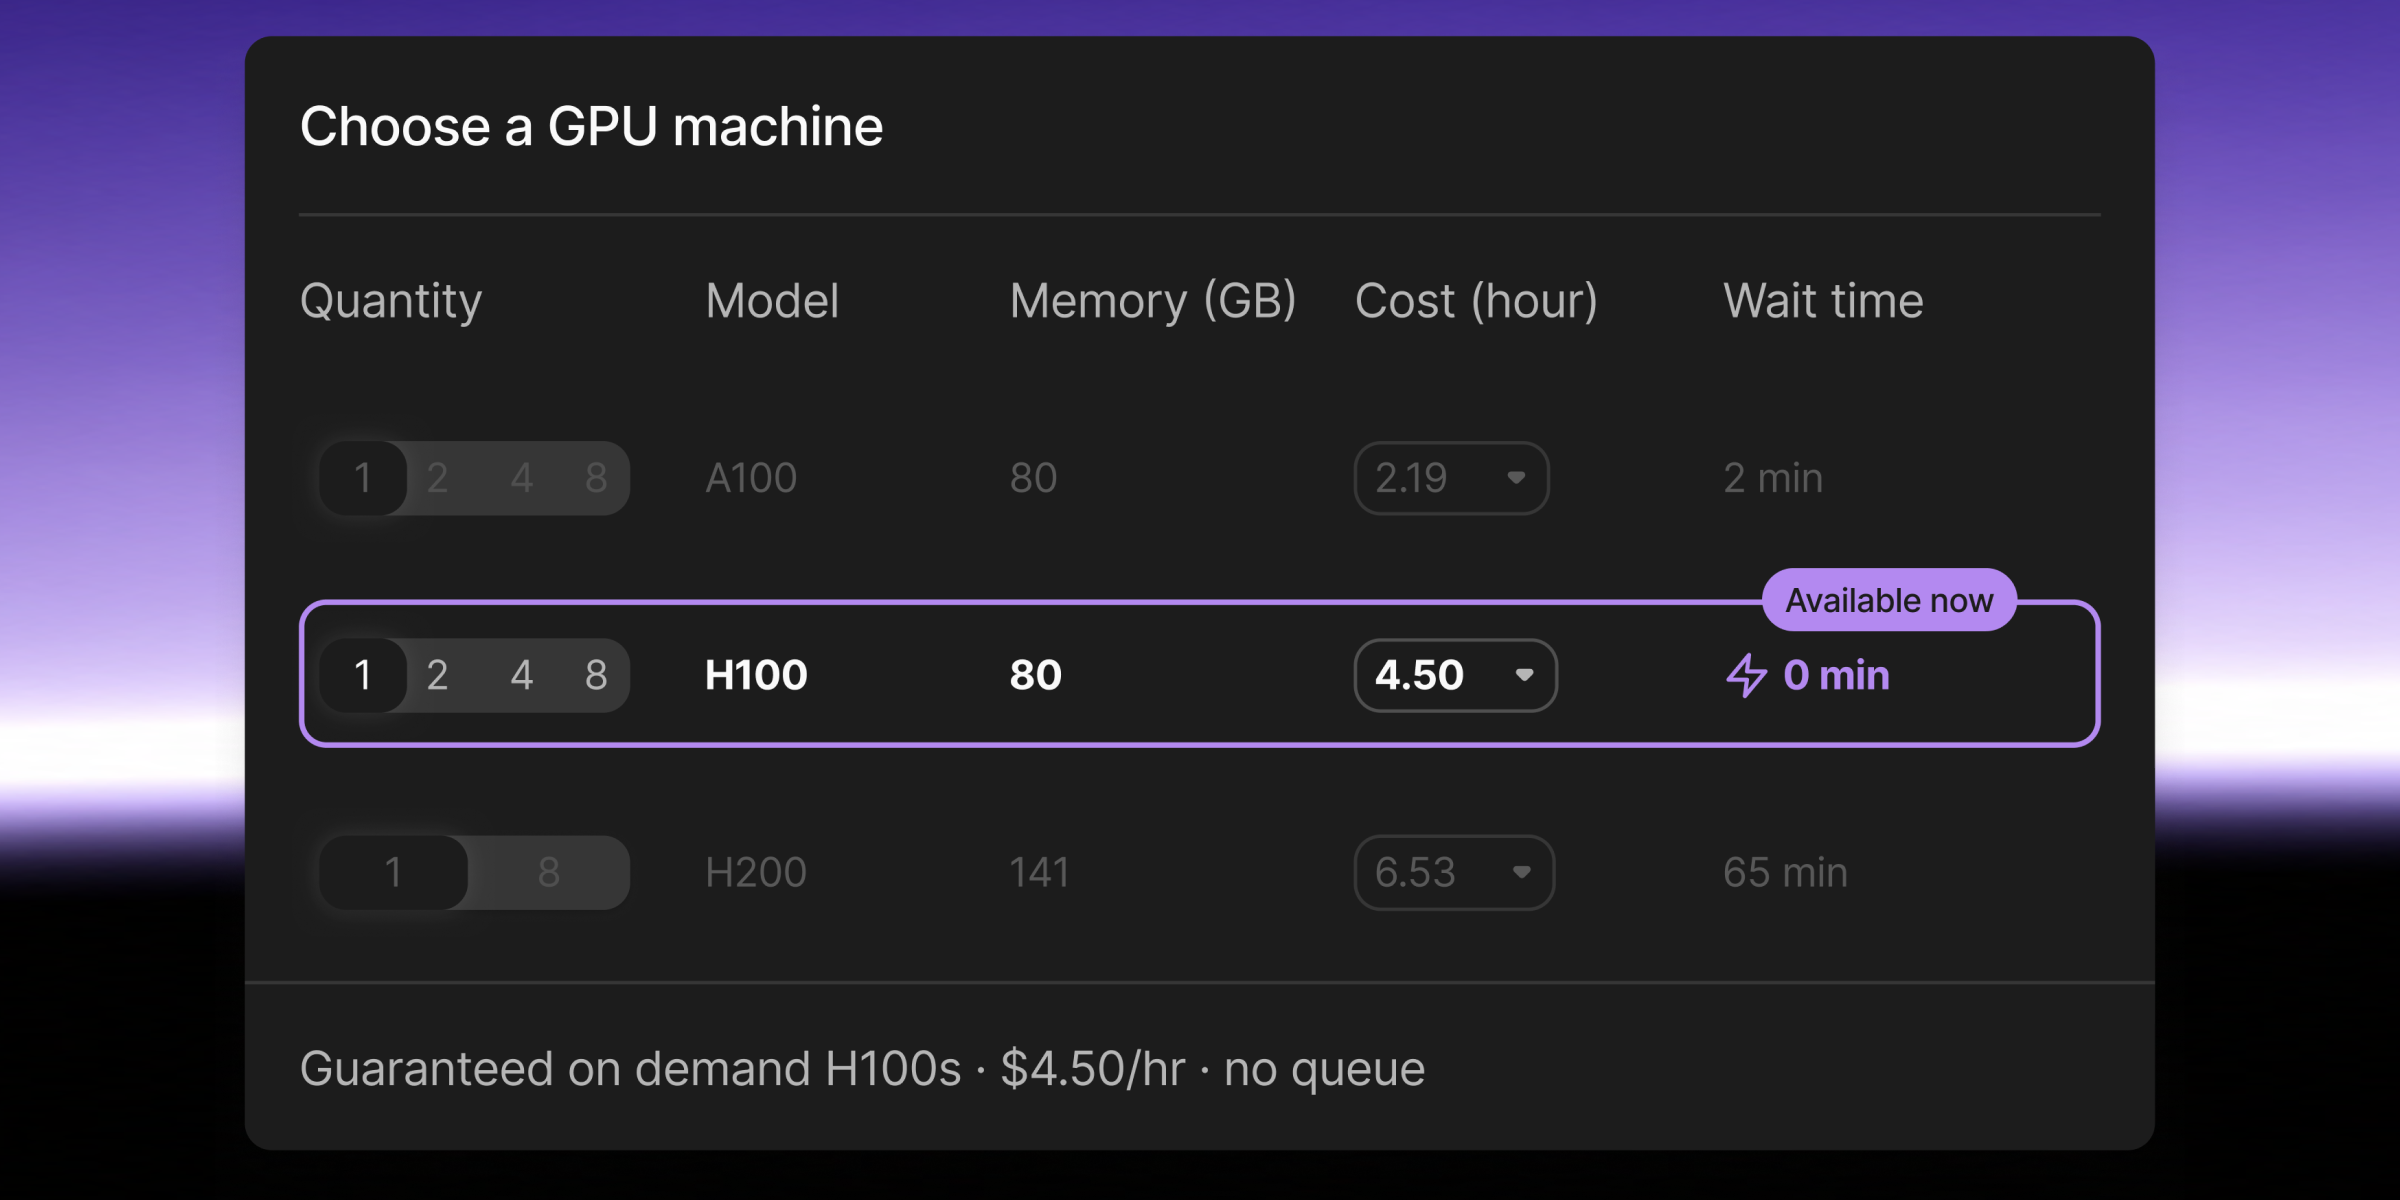
Instant on-demand H100 capacity
Run on AI-optimized, high-performance nodes operated directly by Lightning AI. Our owned fleet also includes B200 and GB300 systems as we expand capacity across hardware generations. Teams can guarantee availability with a 1 year commitment and secure favorable pricing.
Bare-metal NCCL performance
You do not have to choose between infrastructure performance and a managed developer experience. Because we control the host and guest topology, we can align the virtualized environment with the physical hardware underneath it.
Topology-aware multi-node placement
Multi-node jobs are placed on the appropriate switch fabric automatically. Lightning understands the datacenter topology before a workload is scheduled, allowing the platform to place distributed jobs as a single coordinated system rather than a collection of unrelated machines.
Reliable provisioning
Because Lightning controls the hardware, scheduler, and software layer, there are fewer external dependencies between a capacity request and a running machine. When you request an H100, the same infrastructure operator is responsible for delivering it.
Teams can now focus on the research and science that differentiates their business. Lightning handles the stack beneath it, down to the PCI segment.
Numbers never lie
Our full stack is a strategic force multiplier for enterprise teams. This is what the Lightning Cloud can deliver - because we own every layer.
| Lightning Cloud | Everyone else | |
| Price | Starting at $4.50/hr | Starting at $7.90 |
| NCCL Speed (Interconnect) | 460 Gbps | Cap at 300 Gbps |
| Average wait time | <1 min | 60+ min |
| New member onboarding | 1 day | 2 weeks |
Archetype AI is a startup building AI foundation models for understanding the physical world using video, sensor, and other real-world signal data (rather than just text/images) to let AI reason about physical events, movement, and context in real time. They're one of the first applied AI teams building on the Lightning Cloud to train their foundation model, Newton.
"We chose Lightning AI to train our flagship world model, Newton, because we were impressed by their platform and cloud-based Studio workspace. We believe they can speed up our foundation model development, scale up to full training runs, and do so cost-effectively."
- Dong Lin, Principal Research Engineer, Archetype AI
Getting started
We’re now onboarding teams that need experimentation and training infrastructure they can rely on starting on Day 1. Guaranteed on-demand availability starts at $4.50/hour with a 1-year usage commitment. Request access here →